The Grafana Alerting squad operates at the core of the Grafana open-source project (link), and our mission is to provide the most in-depth way to let users manage their alerts. The backend-focused team works closely with customers and the Grafana Cloud teams to make Alerting work on-prem and at infinite scale in Cloud. The team's scope spans both Grafana Alerting and the SLOs product, so engineers get to work across two products that are deeply connected in how they help users detect and respond to problems. Grafana Alerting is trusted by major organizations worldwide, monitoring essential medical devices and critical infrastructure. We thrive on collective creativity and diverse perspectives, every team member is encouraged to contribute ideas that shape our product into a dependable tool. Our domain is quite large, so to get an idea of the kind of work we do, here are some projects we recently worked on: Build distributed systems to scale alert ingestion and delivery of Prometheus-based alerts Unify Alerting setup and delivery to work the same for Grafana and Prometheus-based alerts Build distributed systems to scale alert evaluation of Grafana-managed alerts, reaching over 500 evaluations per second in production. Grafana Alerting is trusted by major organizations worldwide, monitoring essential medical devices and critical infrastructure. We thrive on collective creativity and diverse perspectives, every team member is encouraged to contribute ideas that shape our product into a dependable tool. What You’ll Be Doing: Take an active role in influencing our roadmap and your own career objectives Work with your team to deliver new features, then use the results to iterate and improve. Drive projects from initial ideation all the way to operations once it is in the hands of customers Embrace our open-source culture and contribute to other projects that may not directly fall within your team’s scope Design, build, operate, and maintain critical systems, owning the reliability, performance, and availability Be a part of your team’s on-call rotations and take ownership of the services you’re running Mentor and support other team members, participate in design discussions and collaborate with the team Learn new skills by gaining a deeper understanding of our cloud product and our customers and getting to know the codebase of a large distributed system As we are remote-first and our engineering organization is largely remote, we provide guidance and meet regularly using video calls, so an independent attitude and good communication skills are a must. What Makes You a Great Fit: You are a motivated self starter with a bias towards action You are customer focused We build everything with our users in mind. You have a passion for creating intuitive products that fit customers’ needs Pragmatism: You are able to take on complex challenges and break them down to achieve short feedback loops: to analyze, design, and build modular solutions, deliver MVPs, gather data and feedback and then progress iteratively Collaboration and communication: The smallest unit we have is a team. You’ll be working with your teammates in a fully remote setup. Good communication skills are a must Solid experience with at least one programming language. We use Go, but if you have familiarity with Python, Java, C++, Rust or similar then that translates well Some experience with delivering projects from gathering requirements, brainstorming ideas all the way to shipping a product to the customer’s hands in a self-driven way Some experience with developing software that runs in the Cloud or some experience with systems engineering Experience writing clean, robust, and performant software that is easily maintained by others Compensation & Rewards: In the UK, the compensation range for this role is GBP 103,958 - GBP 124,750. Actual compensation may vary based on level, experience, and skillset as assessed throughout the interview process. All of our roles include Restricted Stock Units (RSUs), giving every team member ownership in Grafana Labs' success. We believe in shared outcomes—RSUs help us stay aligned and invested as we scale globally. Compensation ranges are country specific. If you are applying for this role from a different location than listed above, your recruiter will discuss your specific market’s defined pay range & benefits at the beginning of the process. Why You’ll Thrive at Grafana Labs: 100% Remote, Global Culture - As a remote-only company, we bring together talent from around the world, united by a culture of collaboration and shared purpose. Scaling Organization – Tackle meaningful work in a high-growth, ever-evolving environment. Transparent Communication – Expect open decision-making and regular company-wide updates. Innovation-Driven – Autonomy and support to ship great work and try new things. Open Source Roots – Built on community-driven values that shape how we work. Empowered Teams – High trust, low ego culture that values outcomes over optics. Career Growth Pathways – Defined opportunities to grow and develop your career. Approachable Leadership – Transparent execs who are involved, visible, and human. Passionate People – Join a team of smart, supportive folks who care deeply about what they do. In-Person onboarding - We want you to thrive from day 1 with your fellow new ‘Grafanistas’ to learn all about what we do and how we do it. Balance is Key - We operate a global annual leave policy of 30 days per annum. 3 days of your annual leave entitlement are reserved for Grafana Shutdown Days to allow the team to really disconnect. We will comply with local legislation where applicable. Equal Opportunity Employer: Grafana Labs is an equal opportunities employer. We welcome applications from everyone regardless of race, colour, nationality, origin, caste, sex, gender reassignment identity or expression, sexual orientation, age, religion or belief, disability, veteran status, genetic information, pregnancy, maternity, marital, family or carer status, or any other characteristic which is protected by local law. We believe that equality and diversity build a strong organisation, and we work hard to ensure that is the foundation of our organisation as we grow.
UK visa sponsor
Does Grafana Labs Ltd sponsor visas?
Yes. Grafana Labs Ltd is on the Home Office register of licensed sponsors, so it can sponsor visas, including Skilled Worker visas.
A licence means the employer can sponsor. It doesn't mean every role is open to sponsorship, so confirm with the employer for the role you want.
Current jobs at Grafana Labs Ltd
Grafana Labs is the company behind Grafana Cloud, the fully managed observability platform trusted by more than 10,000 organizations to ensure reliability, resolve incidents faster, and optimize telemetry at scale. Built on open source and open standards and designed for interoperability across any stack, Grafana Cloud brings AI to observability and observability to AI, giving teams (and their agents) unified visibility so they can see, understand, and act on all their disparate data, wherever it lives, and move at the speed of their ambitions. Customers, including Anthropic, Bloomberg, NVIDIA, Microsoft, and Salesforce, rely on Grafana Labs. We are a 100% remote company with team members across 40+ countries, backed by leading investors including Lightspeed Venture Partners, Sequoia Capital, GIC, Coatue, J.P. Morgan, CapitalG, and Lead Edge Capital. Learn more at grafana.com and follow us on LinkedIn and X. We’re scaling fast and staying true to what makes us different: an open-source legacy, a global collaborative culture, and a passion for meaningful work. Our team thrives in an innovation-driven environment where transparency, autonomy, and trust fuel everything we do. You may not meet every requirement, and that’s okay. If this role excites you, we’d love you to raise your hand for what could be a truly career-defining opportunity. This is a remote opportunity and we are looking for candidates from the UK, Sweden, Spain or Germany. About the role: We are looking for a Staff Software Engineer - SRE to help us support our highest value Grafana Cloud customers by increasing the reliability of our Cloud databases that are based on Mimir, Loki, Tempo, and Pyroscope. We provide these databases as a SaaS product from AWS, GCP, and Azure across all regions. The SRE team is embedded within the Mimir, Loki, and Tempo squads and focuses on ensuring that Grafana Cloud’s database products deliver exceptional reliability for our highest-SLA customers. In this role, you will: Partner closely with product engineering squads (embedded model) Own production reliability for high-SLA and complex customer environments Design and implement automation to scale our reliability practices Ensuring our customers meet our SLO targets Define and evolve per-tenant SLOs and reliability models Proactively reduce SLO burn to prevent repeat incidents Serving as a primary escalation point and on-call for relevant incidents Lead customer-impacting incident response and post-incident reviews Contribute to design docs and code reviews Influence feature design to ensure production scalability and operability Build automation to eliminate toil where needed Improve alert quality and reduce noisy escalations We seek a staff software engineer operating at the intersection of customer needs, production systems, and product engineering. We invest heavily in developer productivity. You can use modern AI coding assistants as part of your daily workflow (your choice of tools, within security guidelines), backed by a company-funded usage budget so you can iterate quickly without unnecessary friction. We encourage pragmatic AI-assisted development: faster prototyping, test generation, refactors, documentation, and incident follow-ups—always paired with strong code review and quality standards. You'll also have access to the latest frontier models from OpenAI, Anthropic, and Google. What we seek: 8+ years engineering experience, 4+ in SRE/CRE/production engineering. Strong preference for those with formal customer reliability engineering experience. Strong Kubernetes experience in AWS, GCP, or Azure, and familiarity with infrastructure-as-code tooling (Helm, Terraform, Jsonnet, etc.). Strong experience with technical leadership, leading a team through projects, mentoring other engineers on the team and serving as a force-multiplier Experience operating multi-tenant systems in production Strong experience designing and implementing SLOs Experience with one or more programming languages (e.g. Go, Python, Java, etc) Experience with Linux operating systems internals, and some knowledge of networking, cloud storage, and scaling. Excellent problem-solving and troubleshooting skills. Experience with calmly and actively participating in blame-free Incident Response, following up on actions, and writing high quality PIRs (Post Incident Reviews, a.k.a. post-mortem documents) Ability to reason about performance, scaling, and failure modes Comfortable working within an engineering team where individuals are encouraged to have a strong sense of autonomy and self-direction. Ability to partner deeply with product engineering teams We highly value those who are intellectually curious, who default to transparency, possess a high bias towards action, and who are also kind (this is important!) Your day-to-day will include: Regular 1:1s to with your manager and colleagues Reviewing and creating SLOs, proactively investigating ways in which we can further reduce budget burn for those SLOs, which can be self-directed or as the result of learnings from incidents, and may include improvements to monitoring, automation, increasing self-healing, auto-scaling, etc. Improve observability of customers within their environments Designing and implementing solutions to ensure reliability and scalability of our environments can meet rapidly increasing demands Develop fault-tolerant design patterns ensuring that we are considering reliability at all stages of the service lifecycle. Collaborating with our Engineering Leaders to help define and influence product strategy, roadmaps and technical designs Participate in PR review and collaborating with other engineers on their Design Docs Teach others about Site Reliability Engineering and communicate best practices to be applied early in development of new features and functionality Participate in Incident Response when applicable, including investigation through to resolution, PIR, and communication with customers via Bridge calls where necessary In the UK, the Base compensation range for this role is £103,958 - £124,750. Actual compensation may vary based on level, experience, and skillset as assessed in the interview process. Benefits include equity, bonus (if applicable) and other benefits listed here.LI-Remote
Chrome extension
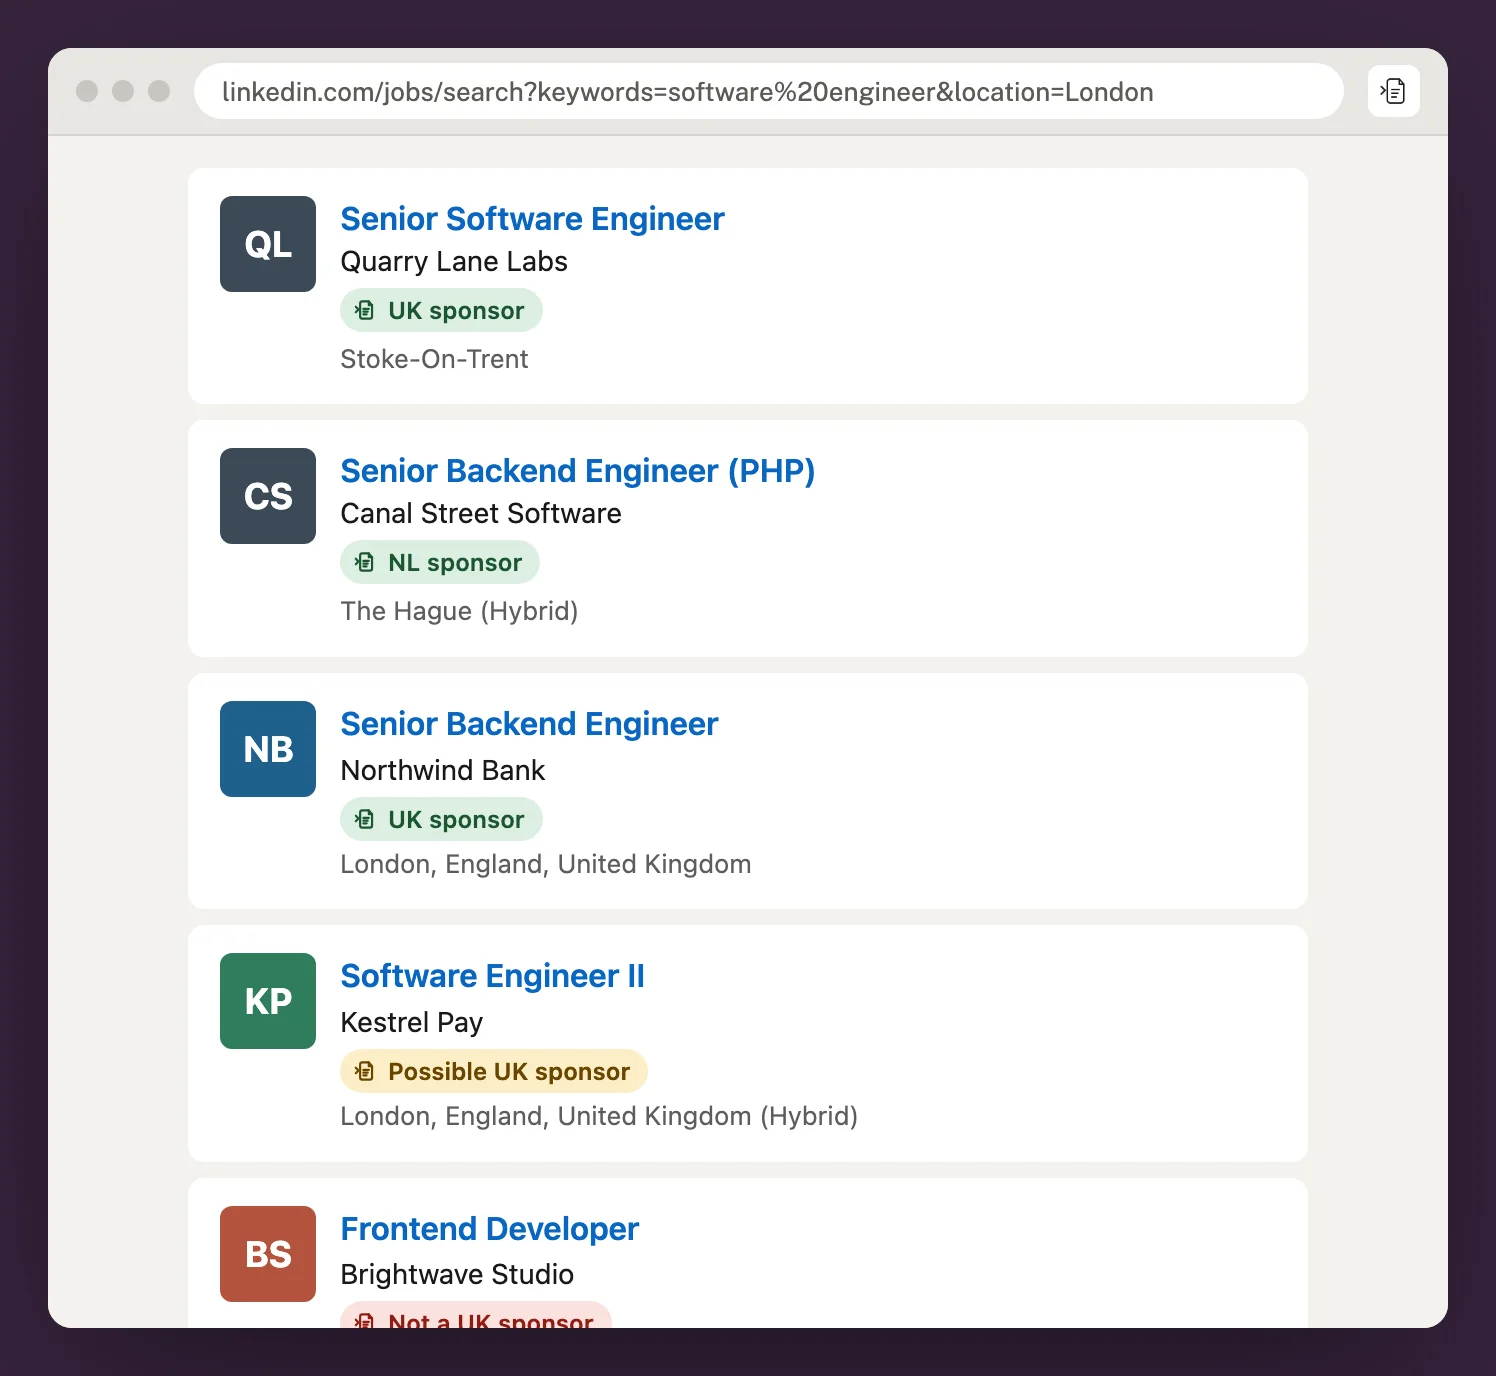
Check sponsors while you browse LinkedIn.
Sponsor badges appear under every employer in LinkedIn, Indeed and Glassdoor search results, so you can see who can sponsor a visa before you open the job.